
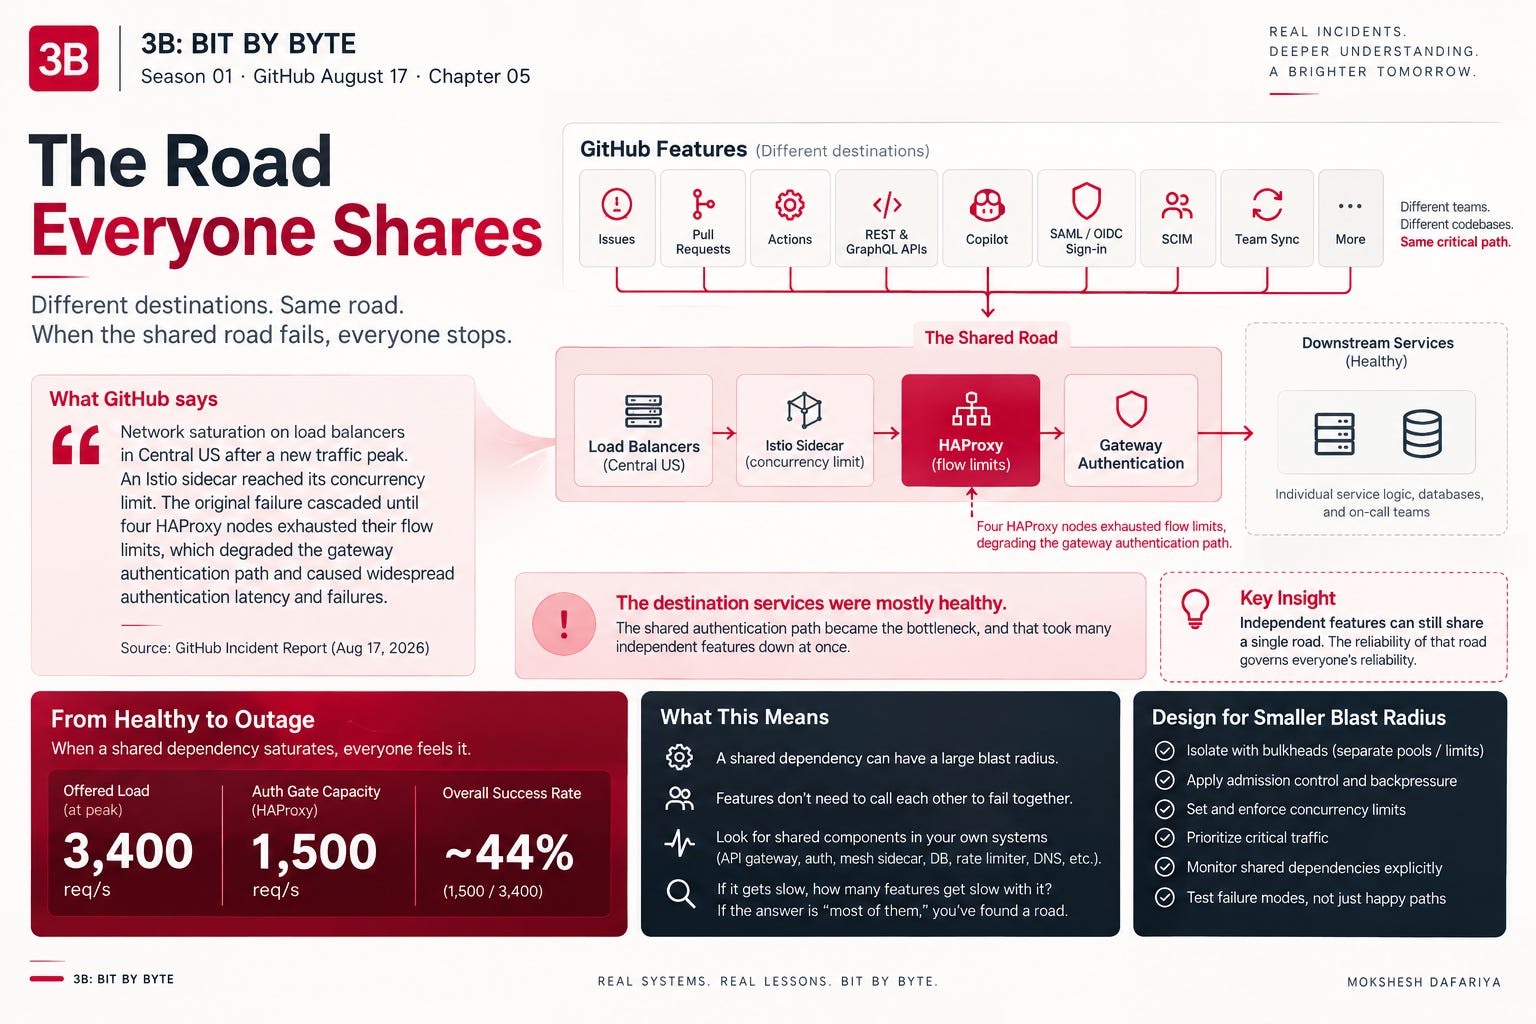
Picture the surface of GitHub as a wall of switches. Issues. Pull Requests. The REST and GraphQL APIs. Actions. Copilot. SAML and OIDC sign-in. SCIM. Team Sync. On a normal day these feel like separate products built by separate teams, and in most ways they are. They have their own code, their own databases, their own on-call rotations.
On the afternoon of August 17, a lot of those switches went dark at roughly the same moment.
If you were only watching the symptoms, this looked like a coincidence too big to be a coincidence. How does the thing that opens an issue break at the same time as the thing that reviews a pull request break at the same time as the thing that hands Copilot a token? These features do not call each other. They do not share a database. Someone new to the incident might reasonably guess that ten things broke, which would mean ten separate bugs all deciding to show up on the same Monday.
That is almost never what happened. And the more interesting question is not “which service broke.” It is “which shared dependency did all of these features quietly route through, and why did that one thing get to take all of them down at once.”
That question is what this chapter is about.
GitHub says
Let me stay strict about sourcing, because that is the whole point of 3B.
GitHub’s incident report describes a chain, not a single snap. The immediate trigger was network saturation on load balancers in the Central US datacenter after a new traffic peak. An Istio sidecar hit its concurrency limit and did not scale the way it should have. Retry logic that was trying to help added more load instead of less.
Then comes the sentence I want to sit with for this chapter. GitHub says the original failure cascaded until four HAProxy nodes exhausted their flow limits, which degraded the gateway authentication path and caused widespread authentication latency and failures.
That is the hinge. The features that fell over included Issues, Pull Requests, the APIs, Actions, Copilot, SAML and OIDC authentication, SCIM, and Team Sync. That is a wide list. But notice what almost every item on it has in common. Before it can do its own job, it has to get one question answered somewhere along the request path: who are you, and are you allowed to do this?
When the authentication path at the gateway degrades, that question stops getting answered quickly, or stops getting answered at all. And a feature that cannot confirm who you are cannot safely let you do anything, even if its own logic is completely healthy. The pull request service did not forget how to show you a diff. It just never got past the front door.
That is what GitHub documents. Four HAProxy nodes run out of flow capacity, the gateway auth path degrades, and authentication latency and failures spread across the surfaces that depend on it. On a platform like this, that is most of them. (Exactly which surfaces routed through that path, and whether they all shared one route or several that happened to sit behind the same saturated layer, is a detail the writeup does not settle, and one I come back to at the end.)
The principle
Here is the principle, stated plainly:
Independent features can still share a single road. A gateway, an authentication path, a network layer. And that shared road, not the features themselves, governs their reliability.
We usually draw architecture diagrams as boxes with clean lines between them, and we admire how decoupled it all looks. But there is almost always a layer underneath the boxes that every request passes through on its way in. Call it the shared critical path. It is the dependency that many otherwise unrelated features route through, and when it degrades, all of them degrade regardless of their own health.
Authentication is a perfect example, because it is invisible until it is not. Nobody lists “auth” as a feature. Users do not think about it. But it sits on the entry road for Issues and Pull Requests and the API and Copilot alike. Saturate that one road and you have not broken one feature. You have broken the intersection every feature drives through.
The word for how far a single failure spreads is blast radius. The August 17 story is, in large part, a story about blast radius. A resource ran out (HAProxy flow limits), it degraded one shared thing (the gateway auth path), and because that shared thing sat on the critical path of so many features, the blast radius grew until it looked like the whole platform.
Translating this to your world
You do not run GitHub. You probably do run something with a shared road in it, and you may not have named it yet.
Think about the request lifecycle for your own service. Before your business logic runs, what does every request touch? An API gateway. An auth service or a token check. A service mesh sidecar. A shared connection pool to the primary database. A rate limiter. A DNS resolver. Any one of those is a candidate shared critical path, which means any one of them is a candidate for a blast radius far larger than its own importance suggests.
The test I use is simple. For each shared component, ask: if this gets slow, how many of my supposedly independent features get slow with it? If the honest answer is “most of them,” you have found a road, not a box. Its reliability is not its own private concern. It is the ceiling on everyone else’s reliability.
The good news is that this is a known problem with known shapes of answers. Isolation patterns exist precisely to shrink blast radius. Bulkheads keep one workload from draining a pool that another workload needs. Cells and separate pools give different tenants or different features their own copy of the shared thing, so saturating one does not starve the rest. The point of all of them is the same: make the road narrower in scope so that when it floods, the flood is contained.
Let’s experiment
Before the code, hold the intersection in your head, because every number below is that picture with instruments attached. The three endpoints are three destinations across town, each with a perfectly clear street of its own. The one shared road is the auth path they all merge onto before they can get anywhere. And the flood is one destination’s traffic swelling until it fills that shared road, so cars headed for the other two, healthy streets and all, sit stuck at the same intersection.
So I built exactly that. It is small enough to run on a laptop, and it ships with this chapter (link at the end of the section). It is not a reconstruction of GitHub’s topology, which is not public. It is a deliberately small model of the one mechanism at issue: a shared bottleneck turning one workload’s overload into everyone’s outage. Three independent endpoints, one shared auth gate in front of them:
/notes    (200/s)  \
/tasks    (200/s)  ->  AUTH GATE (30 slots, ~1500 auth/s)  ->  handler (5ms)
/profile  (3000/s) /
The endpoints are /notes, /tasks, and /profile: three separate handlers with zero shared logic, each doing a trivially fast 5ms slice of its own work. That work runs only after the auth slot is released, so the handlers never add to the crowding at the gate. Nothing about them is fragile, and nothing connects them.
The auth gate is the one thing they share. It is a semaphore with 30 slots, and every request has to pass it before reaching its handler. Each auth check holds a slot for 20ms, so the gate can clear only about 1,500 auth checks per second in total, across all three endpoints. A request that cannot get a slot within 50ms is turned away: a timeout at the gate, not a fault in any handler behind it. The request never reached one.
The load is open-loop and flat, one generator per endpoint that never backs off. /notes and /tasks are light and innocent, 200 requests per second each. /profile floods at 3,000 per second, which by itself is twice the entire gate’s capacity.
First run, all three share the one gate. Here is the actual output:
Endpoint   Offered  Success  p50 lat  p95 lat
/notes     200      39%      71ms     83ms
/tasks     200      44%      72ms     94ms
/profile   3000     43%      72ms     86ms
Read the success column first. /profile is flooding, so of course it fails most of what it offers. But look at /notes and /tasks. Each is offering a trivial 200 requests per second, each has a handler that is perfect and untouched, and each is succeeding only about 40% of the time, right alongside the flood. Their latency has tripled too, from a healthy 25ms to over 70ms. Nothing about those two endpoints changed. They simply share /profile‘s road, and /profile filled it. The three success rates fall together, in lockstep, because they were never really three independent systems. They are three tenants of one road.
The specific number is not arbitrary. The gate clears about 1,500 of the 3,400 requests offered each second, roughly 44% overall. All three endpoints pour into the same queue for that one gate, so over any window each endpoint’s share of the requests that get through tracks its share of the requests coming in. That is why all three land near the same 44% success rate, instead of the flood crowding the light endpoints out entirely, and why a light, innocent endpoint pays nearly the same rate as the flood it happens to share a gate with. The exact split drifts run to run with scheduling and timing, but the shape holds.
Now give each its own lane. Same load, same flood, same handlers, but each endpoint gets its own gate instead of sharing one:
Endpoint   Offered  Success  p50 lat  p95 lat
/notes     200      100%     25ms     28ms
/tasks     200      100%     25ms     28ms
/profile   3000     16%      71ms     77ms
The picture splits in two. /notes and /tasks snap back to 100% success at 25ms, because their gates were never crowded to begin with. /profile still tanks, because it genuinely offers far more than one lane can clear: each endpoint’s own gate holds a third of the slots (10 of the 30), so it passes only about 500 auth checks a second, and /profile is still offering 3,000. But now that failure is its own. The flood is exactly as big as before. The only thing that changed is how far the damage reaches. That is a bulkhead: not more capacity, just a wall that keeps one workload’s flood from draining everyone else’s road.
One honest note on those tables: unlike the earlier chapters, there is no modeled number here. The offered rates, the success rates, and the latencies are all measured end to end from real goroutines passing through a real semaphore with real auth waits. Each table is a single run, measured over a three-second window after a one-second warmup, with latency recorded only for requests that succeeded. The whole result is the per-endpoint contrast between the two arrangements, and you can reproduce it.
The code is in the season repo on GitHub, under 05-shared-bottleneck/. Run go run ./minimal for the bare shared bottleneck and one plain table, go run . for the full shared-vs-bulkhead run above, or go run ./tui to dial /profile‘s flood yourself and toggle the arrangement live: watch all three success bars fall together on the shared gate, then press one key and watch /notes and /tasks jump back to full while only /profile stays down. The reasoning stands on its own too: a shared dependency sets the ceiling on everyone who routes through it, and the surest way to shrink a blast radius is to stop sharing the thing that carries it.
What we don’t know
I want to be honest about the edges of the evidence, because that honesty is the discipline.
GitHub tells us four HAProxy nodes exhausted their flow limits and that this degraded the gateway auth path. What the writeup does not hand us is the exact topology: how many features shared those specific nodes, whether every affected surface authenticated through the same path or through several that happened to sit behind the same saturated layer, or what the flow limit numbers actually were. My lab reproduces the mechanism, a shared bottleneck spreading a blast radius, but it is my model of the shape, not a recovered copy of GitHub’s internals. When I say “authentication was the shared road,” I am reasoning from the documented symptom list plus a plainly stated cause. I am not claiming to have seen their config.
That gap is fine. Naming it is what keeps the reasoning trustworthy.
Next in 3B: Bit By Byte
We have been treating the traffic as if it just arrived. It did not entirely. Some of it was manufactured by clients that were trying to be helpful. Next, in Chapter 6, The Copilot Retry Storm, we follow the thread of how a latent client retry bug amplified one service’s traffic from its normal 9,000 requests per second toward 100,000, and what a self-inflicted flood teaches you about the difference between load you receive and load you create.
If you want the whole teardown, one question at a time, subscribe and come with me.